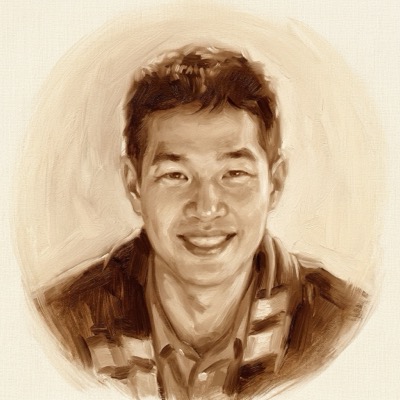
Mark Chen
Chief Research Officer, OpenAI
About
Mark Chen is the Chief Research Officer at OpenAI, where he oversees the company's research priorities and direction toward artificial general intelligence. Before joining OpenAI in 2018, he worked as a quantitative trader at Jane Street Capital and Integral Technology. A graduate of MIT with a degree in Mathematics with Computer Science, Chen has been instrumental in developing landmark AI systems including DALL-E, Codex, and GPT-4, and played a key role in building OpenAI's o1 and o3 reasoning models.
Key Contributions
- Co-led DALL·E, one of the first systems to make text-to-image generation legible to the public
- Helped build Codex, connecting language-model research to practical code generation and developer tools
- Contributed to GPT-4-era multimodal and frontier-model research before moving into top research leadership
- Worked on OpenAI's reasoning-model line, including the o-series shift from next-token fluency toward deliberative problem solving
- Became OpenAI's Chief Research Officer, putting him in charge of research direction at one of the most consequential closed AI labs
- His low public profile contrasts with the power of the role, raising the broader question of how much frontier-AI research accountability depends on company insiders
Videos & Interviews
Connections
Ilya Sutskever
CollaboratedCo-founder, Safe Superintelligence Inc.
Chen is the first author of 'Evaluating Large Language Models Trained on Code' (2021), the Codex paper that turned a language model into a programmer's tool; Sutskever's name sits among its fifty-eight authors, near the end where a chief scientist signs. The paper marks a shift in what counts as evidence — from how well a model predicts to what it can be measured actually doing. Chen went on to hold the research ground Sutskever once held, as OpenAI's chief research officer, with almost none of the public visibility that came with it.
arxiv.org
Terence Tao
In conversationProfessor of Mathematics, UCLA
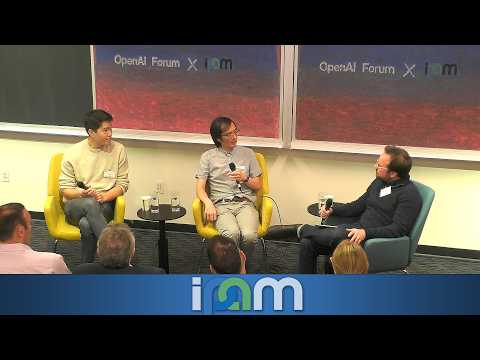
By the IPAM fireside on this site it was their third conversation in as many years, and the moderator opened by reminding Tao of his earlier verdict on what the models were worth to mathematics: something like a very ineffective graduate student. That is the value of the series — Chen comes from a lab building models trained to reason, Tao from a practice where a proof is either checked or it is nothing, and the annual re-run turns a disagreement into a measurement. Tao's interest is unusually concrete: he uses these systems and reports what they get wrong.
youtube.com

